Master Python for Data Science: 5 Libraries by Mid-2026
Advertisements
To excel in data science by mid-2026, mastering five core Python libraries—NumPy, Pandas, Matplotlib, Scikit-learn, and TensorFlow/PyTorch—is critical for processing, analyzing, visualizing data, and building robust machine learning models.
The landscape of data science is evolving at an unprecedented pace, demanding professionals who are not just proficient but truly expert in their tools. If your goal is to be job-ready and highly competitive in this field by mid-2026, then Learning Python for Data Science: 5 Essential Libraries to Master by Mid-2026 (Time-Sensitive) is not just a suggestion, it’s a strategic imperative. This guide will navigate you through the crucial Python libraries that form the bedrock of modern data science, ensuring you build a robust skill set that employers actively seek.
The foundational power of NumPy for numerical computation
NumPy, short for Numerical Python, is the bedrock of almost all higher-level tools in Python’s data science ecosystem. It provides powerful N-dimensional array objects and sophisticated functions for numerical operations. Understanding NumPy isn’t just about syntax; it’s about grasping the core mechanisms that make complex calculations both efficient and scalable.
Efficient data manipulation is paramount in data science. NumPy arrays are significantly faster and more memory-efficient than standard Python lists, especially when dealing with large datasets. This efficiency is crucial for tasks ranging from simple statistical calculations to complex linear algebra operations that underpin many machine learning algorithms.
Why NumPy is indispensable
- Performance: Optimized for speed, NumPy operations are often implemented in C or Fortran, leading to significant performance gains over native Python structures.
- Foundation for other libraries: Pandas, SciPy, and Scikit-learn all build upon NumPy arrays as their primary data structure, making its mastery a prerequisite.
- Mathematical functions: A comprehensive collection of mathematical functions for array operations, including linear algebra, Fourier transforms, and random number generation.
Mastering NumPy involves more than just knowing how to create arrays. It includes understanding array indexing, slicing, broadcasting, and vectorized operations. These concepts allow you to write concise, efficient, and readable code for data preprocessing and numerical analysis, which are daily tasks for any data scientist. Without a solid grasp of NumPy, working with larger datasets and more complex models becomes cumbersome and inefficient.
In essence, NumPy provides the raw horsepower for numerical computing in Python. By mid-2026, a data scientist is expected to not only use NumPy but to leverage its capabilities to optimize their data pipelines and computations. Its role as the universal array standard in scientific Python makes it an unavoidable and highly valuable skill.
Pandas: Your go-to for data manipulation and analysis
If NumPy is the engine, Pandas is the steering wheel and dashboard for data scientists. It introduces two crucial data structures: Series and DataFrame, which are designed for handling tabular data with labels. Pandas transforms raw, often messy, data into structured, analyzable formats, making it an absolute cornerstone for exploratory data analysis (EDA) and data preparation.
Data cleaning, transformation, and aggregation are daily routines in data science. Pandas excels in these areas, offering intuitive and powerful functionalities for tasks like handling missing data, merging datasets, filtering rows, and performing group-by operations. Its SQL-like capabilities make it highly accessible for those with database experience, streamlining the transition to Python-based data workflows.
Core functionalities to master in Pandas
- DataFrames and Series: Understanding their creation, indexing, and basic operations.
- Data cleaning: Handling missing values (
.fillna(),.dropna()), duplicate data, and data type conversions. - Data transformation: Applying functions (
.apply(),.map()), pivoting, melting, and reshaping data. - Data aggregation: Using
.groupby()for powerful summary statistics and aggregations. - Input/Output operations: Reading and writing data from various formats like CSV, Excel, SQL databases, and JSON.
The ability to efficiently manipulate and analyze data with Pandas directly impacts the speed and accuracy of your data science projects. By mid-2026, employers will expect data scientists to not only know Pandas but to be able to use it to quickly derive insights, prepare features for machine learning models, and automate repetitive data tasks. Its rich API and active community ensure that it remains at the forefront of data manipulation tools.
From initial data loading to the final stages of feature engineering, Pandas provides an incredibly versatile toolkit. Its integration with NumPy ensures high performance, while its intuitive syntax lowers the barrier to entry for complex data operations. For any aspiring data scientist, deep proficiency in Pandas is non-negotiable for practical, real-world applications.
Matplotlib and Seaborn: Visualizing data for insights
Data without visualization is like a story without words – it lacks impact and clarity. Matplotlib is the foundational plotting library in Python, providing a flexible and comprehensive framework for creating static, animated, and interactive visualizations. While often considered low-level, its power lies in its customizability, allowing for precise control over every aspect of a plot.
Seaborn, built on top of Matplotlib, offers a higher-level interface for drawing attractive and informative statistical graphics. It simplifies the creation of complex visualizations, making it easier to explore relationships between variables and identify patterns in data. Together, Matplotlib and Seaborn form an essential duo for communicating data-driven insights effectively.
Key visualization techniques to master
- Basic plots with Matplotlib: Line plots, scatter plots, bar plots, and histograms.
- Statistical plots with Seaborn: Box plots, violin plots, heatmaps, pair plots, and regression plots.
- Customization: Adjusting labels, titles, legends, colors, and styles for professional-looking plots.
- Subplots: Arranging multiple plots in a single figure for comparative analysis.
Effective data visualization is not just about making pretty graphs; it’s about telling a compelling story with data. It helps in identifying outliers, understanding distributions, and uncovering correlations that might be missed in raw numerical data. By mid-2026, data scientists are expected to produce clear, insightful, and publication-ready visualizations that support their analysis and model explanations.
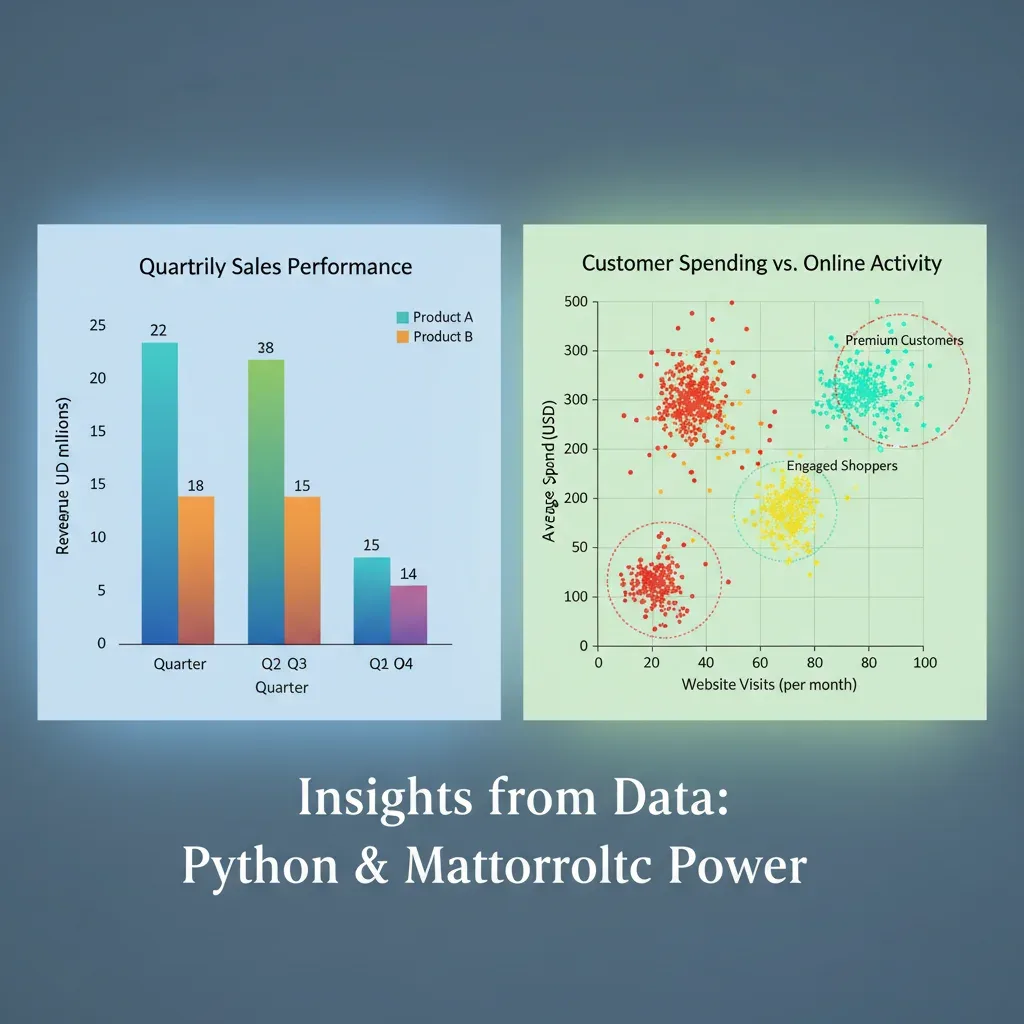
The synergy between Matplotlib and Seaborn allows for both granular control and rapid prototyping of visualizations. Learning to choose the right plot type for your data and effectively convey your findings is a critical skill. This combination empowers you to transform complex datasets into understandable visual narratives, a skill highly valued in any data-driven role.
Scikit-learn: The workhorse for machine learning
Scikit-learn is arguably the most popular and comprehensive machine learning library in Python. It provides a consistent interface for a vast array of supervised and unsupervised learning algorithms, along with tools for model selection, preprocessing, and evaluation. For anyone looking to implement machine learning solutions, Scikit-learn is an indispensable asset.
From classification and regression to clustering and dimensionality reduction, Scikit-learn covers the core algorithms that data scientists use daily. Its well-documented API and ease of use make it an excellent choice for both beginners and experienced practitioners. Mastering Scikit-learn means you can build, train, and evaluate predictive models with confidence and efficiency.
Essential Scikit-learn modules and concepts
- Preprocessing: Scaling, encoding categorical features, handling missing values.
- Supervised learning: Linear regression, logistic regression, decision trees, random forests, support vector machines (SVMs).
- Unsupervised learning: K-means clustering, principal component analysis (PCA).
- Model selection: Cross-validation, hyperparameter tuning (GridSearchCV, RandomizedSearchCV).
- Evaluation metrics: Accuracy, precision, recall, F1-score, ROC-AUC for classification; R-squared, MSE for regression.
By mid-2026, a data scientist is expected to not only apply these algorithms but also understand their underlying principles, strengths, and limitations. Scikit-learn’s unified interface makes it easier to compare different models and select the best one for a given problem. Proficiency here demonstrates a practical understanding of machine learning workflows, from data preparation to model deployment.
The library’s emphasis on interoperability with NumPy and Pandas further solidifies its position in the data science ecosystem. Being able to seamlessly integrate data preparation with model building is a hallmark of an efficient data scientist. Scikit-learn empowers you to focus on the problem at hand, rather than wrestling with algorithm implementations, accelerating your path to delivering valuable insights.
TensorFlow and PyTorch: Deep learning powerhouses
As data science increasingly embraces complex patterns and unstructured data, deep learning has become a critical skill. TensorFlow and PyTorch are the two leading open-source deep learning frameworks, enabling the construction and training of neural networks for tasks like image recognition, natural language processing, and advanced forecasting. While different in their approaches, mastering at least one is crucial.
TensorFlow, developed by Google, is known for its production readiness and scalability, often used in large-scale deployments. PyTorch, championed by Facebook’s AI Research lab, is favored for its flexibility and ease of debugging, making it a popular choice for research and rapid prototyping. Both offer dynamic computation graphs, extensive tooling, and strong community support.
Key areas to focus on for deep learning mastery
- Neural network architectures: Understanding feedforward networks, convolutional neural networks (CNNs), and recurrent neural networks (RNNs).
- Building models: Defining layers, activation functions, loss functions, and optimizers.
- Training process: Managing epochs, batch sizes, learning rates, and early stopping.
- Transfer learning: Leveraging pre-trained models for new tasks to accelerate development.
- Deployment considerations: Understanding how to save and load models for inference in production environments.
By mid-2026, the demand for data scientists capable of building and deploying deep learning models will only intensify. Whether you choose TensorFlow (perhaps with its high-level Keras API) or PyTorch, the ability to work with large datasets, leverage GPUs, and develop sophisticated models will set you apart. These frameworks are not just libraries; they are comprehensive ecosystems for cutting-edge AI.
The choice between TensorFlow and PyTorch often comes down to personal preference or project requirements. However, the core concepts of deep learning remain consistent across both. Investing time in either framework now will ensure you are well-equipped to tackle the most challenging and impactful data science problems in the coming years, making you highly valuable in the job market.
Strategic learning paths and continuous growth
Mastering these five Python libraries by mid-2026 requires a strategic approach beyond just learning syntax. It involves understanding the underlying mathematical concepts, practicing with real-world datasets, and continuously building projects that demonstrate your capabilities. The data science field is dynamic, so continuous learning is not just recommended, it’s essential.
Start with a strong foundation in Python programming, then progressively move through NumPy and Pandas for data manipulation. Once comfortable, dive into Matplotlib and Seaborn to visualize your findings. After solidifying these skills, tackle Scikit-learn for traditional machine learning, and finally, explore TensorFlow or PyTorch for deep learning applications. This structured approach ensures a comprehensive skill set.
Tips for accelerating your learning
- Project-based learning: Apply each library to small projects to reinforce understanding and build a portfolio.
- Official documentation: Refer to the official documentation for in-depth understanding and best practices.
- Online courses and communities: Leverage platforms like Coursera, edX, and Kaggle for structured learning and peer support.
- Contribute to open source: Engaging with open-source projects can deepen your understanding and connect you with the community.
The time-sensitive nature of this goal means prioritizing hands-on experience over passive learning. Actively coding, debugging, and refining your projects will embed the knowledge more deeply than simply watching tutorials. Seek out datasets from various domains to broaden your problem-solving experience and adaptability.
Furthermore, understanding the business context of your data science projects is as crucial as technical proficiency. Knowing how to translate analytical insights into actionable business strategies will elevate your value beyond just a coder. By mid-2026, the most sought-after data scientists will be those who can not only wield these powerful libraries but also drive tangible results for organizations.
| Key Library | Primary Function |
|---|---|
| NumPy | Efficient numerical computing with N-dimensional arrays. |
| Pandas | Data manipulation, cleaning, and analysis with DataFrames. |
| Matplotlib/Seaborn | Creating compelling data visualizations for insights. |
| Scikit-learn | Implementing traditional machine learning algorithms. |
Frequently asked questions about Python for data science
Why is Python the preferred language for data science?▼Python’s popularity stems from its simplicity, extensive library ecosystem (like NumPy, Pandas, Scikit-learn), and strong community support. Its versatility allows it to handle everything from data collection and preprocessing to advanced machine learning and deployment, making it a comprehensive tool for data scientists.
How long does it take to master these 5 Python libraries?▼While basic proficiency can be achieved in a few months, true mastery by mid-2026 requires consistent practice and project application. Expect to dedicate significant time, potentially 6-12 months of focused learning and hands-on work, to comfortably apply these libraries to complex data science problems.
Should I learn both TensorFlow and PyTorch?▼It’s generally recommended to deeply learn one first, typically the one most relevant to your career goals or current projects. While both are powerful, mastering one framework thoroughly is more beneficial than having a superficial understanding of both. You can always learn the other later if needed.
What are the best resources for learning these libraries?▼Official documentation is invaluable. Additionally, platforms like Coursera, edX, and DataCamp offer structured courses. YouTube tutorials, Kaggle notebooks, and dedicated books also provide excellent learning paths. Hands-on practice through personal projects is the most effective way to solidify your understanding.
How do these libraries contribute to job readiness?▼These libraries cover the entire data science workflow: data manipulation (NumPy, Pandas), visualization (Matplotlib, Seaborn), traditional machine learning (Scikit-learn), and deep learning (TensorFlow/PyTorch). Proficiency in them demonstrates a comprehensive skill set highly sought after by employers, directly impacting your job readiness and career prospects.
Conclusion
The journey to becoming a proficient data scientist by mid-2026 is both challenging and rewarding. By strategically focusing on Learning Python for Data Science: 5 Essential Libraries to Master by Mid-2026 (Time-Sensitive)—namely NumPy, Pandas, Matplotlib/Seaborn, Scikit-learn, and either TensorFlow or PyTorch—you are building a robust and highly marketable skill set. These libraries are not just tools; they are the fundamental building blocks for extracting insights, building predictive models, and innovating in the data-driven world. Embrace continuous learning, engage in practical projects, and stay curious, and you will be well-positioned to thrive in the dynamic field of data science.